Collecting knowledge was never the problem. Activating it at the right moment - that’s the problem.
I spent years collecting knowledge. First Notion with a Second Brain, neatly structured according to PARA and CODE. Then the switch to Obsidian - hundreds of Markdown notes, links, daily notes, backlinks. Quick capture from my phone works by now; mobile retrieval is still an open question.
The tools got better. Maintenance stayed my bottleneck. It wasn’t the tool - it was that I was permanently behind: capturing I can manage; distilling, linking and pruning, not so much.
That isn’t a personal failure. It’s structural. And this is exactly where something is shifting in my setup right now - not because I’ve become more disciplined, but because the division of labor has changed.
Why classic PKM fails structurally
The methods aren’t wrong. They were just built for a world in which knowledge was scarce and attention was plentiful. Today it’s the other way around.
Zettelkasten works - if you’re Luhmann
Niklas Luhmann left behind about 90,000 index cards, the foundation of practically his entire sociology. In 2017, Sönke Ahrens wrote the system down for the rest of the world in “How to Take Smart Notes”: atomicity, linking, your own words, fleeting/literature/permanent notes. Those terms, by the way, are Ahrens’ extension - Luhmann himself never used them.
The principles are right. The problem is execution. The “Evernote effect”, as zettelkasten.de describes it, hits every growing system: the more you collect, the more energy maintenance eats up - until the return no longer justifies the upkeep. Which of us has 30 minutes a day to distill our thoughts? Exactly.
Second Brain diagnosed its own problem
With “Building a Second Brain” (CODE: Capture-Organize-Distill-Express, PARA: Projects-Areas-Resources-Archive), Tiago Forte shaped an entire generation. And he named the knowledge-graveyard problem himself - roughly: a Second Brain shouldn’t be a warehouse but a factory that turns ideas into concrete results. In Forte’s own words: “information only becomes knowledge when we put it to use”.
The diagnosis is precise. Except - the solution once again demands human discipline. Distill and Express are work. A lot of work. And it’s at exactly these two steps that the system fails in practice, not at capture.

Modern tools, old division of labor
Obsidian, Notion, Tana - all of them got AI features over the last two years. Smart Connections finds semantic neighbors. Copilot for Obsidian answers questions about the vault. Notion AI provides a query layer that often doesn’t understand database relations and doesn’t even see external embeds. Tana goes furthest with agent nodes, triggers and supertags. But even Tana is rule-based; it doesn’t think on its own.
These are all assistants. None of them is a maintainer. None of them writes new notes unprompted, condenses topics, spots contradictions between old and new thoughts, or archives dormant material. The work stays with you - the tools just make it more comfortable.
The shared blind spot
Whether Zettelkasten, Second Brain or modern PKM tooling: every one of these methods assumes a disciplined human maintainer. Someone who regularly tidies up, links, condenses, prunes. That person exists in theory. In practice, there’s a knowledge worker with a full calendar who’s glad to capture anything at all.
The methods didn’t fail. The assumption that a human can be author, curator and archivist at the same time failed.
The shelves aren’t the problem. Not the tags, not the links, not the folders. The problem is the distribution of roles. And that’s exactly where we have to start over.
Mycel - the new division of labor
If maintainers are rare, the role has to disappear - not the work. That’s exactly the mental shift Andrej Karpathy packed into a post on April 2, 2026: LLMs as curators of personal knowledge bases. Almost 20 million views, followed shortly by a gist with the architecture sketch. Karpathy describes his own wiki: about 100 articles, roughly 400,000 words, entirely compiled and maintained by the LLM - he barely touches it himself anymore.

The architecture I developed for myself in parallel, and sharpened against Karpathy’s sketch, runs in three layers:
raw/- immutable sources. Articles, transcripts, screenshots, papers. The LLM only reads here. Nothing ever gets written.wiki/- compiled knowledge. Source pages per source, entity pages per person/organization/product, concept pages per idea, synthesis pages that weave several sources together, and question pages that track open questions. Written entirely by the LLM.- Schema/skills - the rules the work follows. Which page types exist, how linking works, what a good concept page format looks like. The schema is alive and gets sharper with every ingest.
The difference from classic PKM isn’t “more automation”. It’s a different distribution of roles. I decide what comes in and which questions I have for the material. The LLM distills, links, maintains.
Why Mycel?
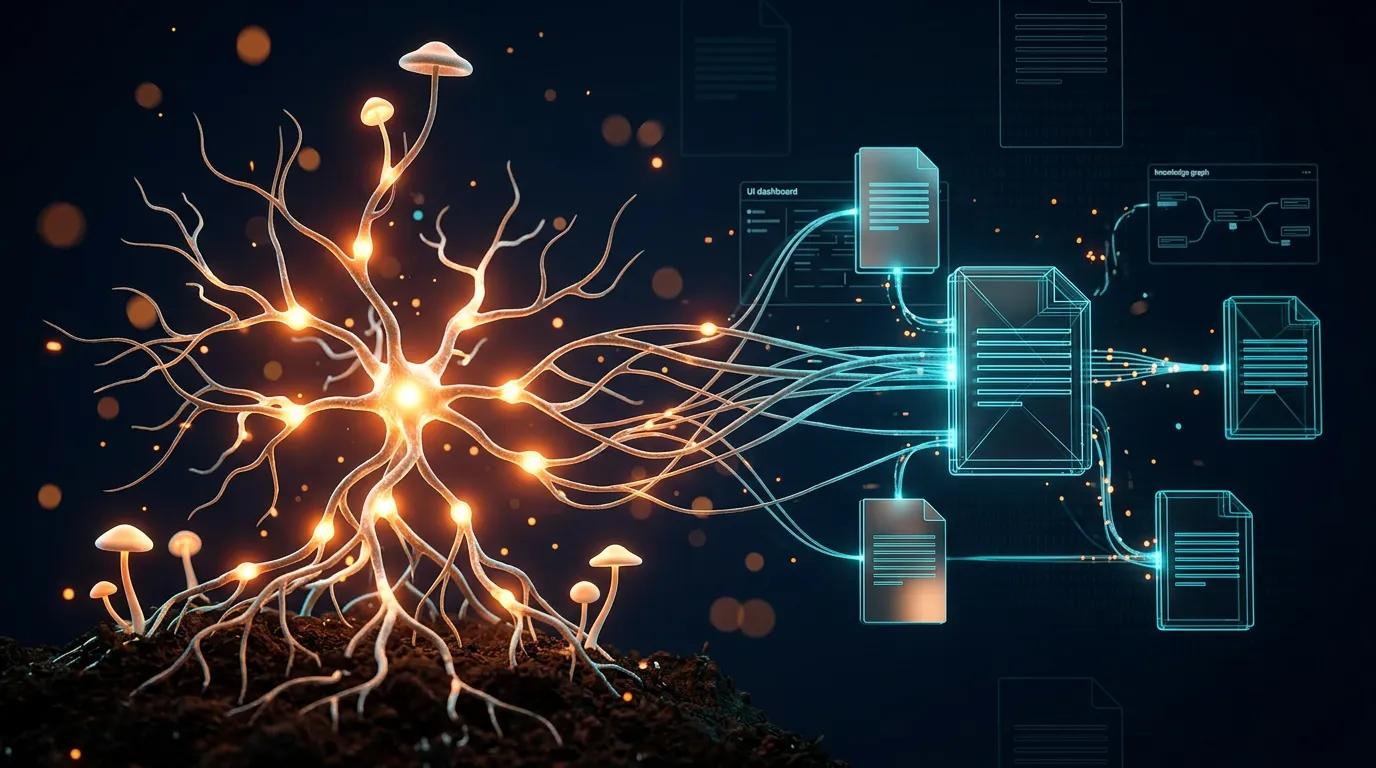
Because the metaphor is precise. A mycelium is the underground web of threads a fungus grows. It takes up nutrients, connects with everything within reach and eventually forms fruiting bodies - the visible mushrooms we think of as “the fungus”.
| Biology | Knowledge system |
|---|---|
| Taking up nutrients | Reading in sources (raw/) |
| Hyphae interconnect | Wikilinks between pages |
| Organic growth | Every ingest densifies the network |
| Fruiting bodies | Syntheses and concepts as visible results |
| Symbiosis | Human curates, machine compiles |
Two of these properties carry the whole architecture:
Compound growth. Mycelia don’t grow linearly, they grow exponentially. In my practice, a new source typically touches 5 to 20 existing pages: it updates entities, sharpens concepts, opens or closes questions. The value doesn’t lie in the number of entries but in the density of connections. Compound over completeness.
Invisible infrastructure. Most of a mycelium lies underground. The most valuable thing about the wiki isn’t the individual summary I see on top. It’s the network of cross-references, contradictions between sources and the open questions in between. The fruiting bodies - syntheses, concept pages - are just the visible tip.
The human doesn’t curate less. They just curate differently: at the level of questions, not at the level of notes.
That’s the break. I no longer maintain notes - I maintain the direction. What am I interested in right now? Which questions are open? Where are the contradictions? The LLM takes over the part humans structurally can’t scale: consistently updating every edge, every single time new material comes in somewhere.
Which leaves one question that comes up as soon as you’ve seen the system - especially for anyone who has already built things with LLMs: if the LLM compiles a wiki from the raw/ folder, isn’t that just RAG with extra steps?
Compiled knowledge isn’t RAG
Before we get to the actual point - retrieval - it’s worth taking a short technical detour. Otherwise the RAG question just hangs in the air, and it deserves a clear answer. No, this isn’t RAG. The difference isn’t the number of steps but the point in time when synthesis happens. RAG thinks while answering. Compiled knowledge has already done the thinking before the question was asked.
Before we go deeper: “compiled knowledge” isn’t an established technical term. You won’t find it in any textbook, and it isn’t a fixed term in the LLM community either. The framing goes back mainly to Karpathy’s compiler analogy from April 2026 - raw sources are treated like source code: compile first, then execute. The result is denser, more structured, faster to retrieve. I’m borrowing the term because it captures the principle well.
What RAG actually does
RAG splits documents into chunks, runs every chunk through an embedding model and stores the vectors in a vector store. At query time, the question gets embedded too, the store returns the most similar chunks, and the LLM gets those snippets as context. Everything happens just in time. The actual thinking - what does this mean, how does it fit together, where does it contradict itself - gets delegated to the model all over again with every single query.
I mean classic, non-agentic RAG here. Modern hybrid search, re-ranking or agentic RAG approaches blur the line - the difference then becomes one of degree, not of principle.
What compiled knowledge does differently
Synthesis happens at ingest, not at answer time. A new source doesn’t get bluntly chopped up and vectorized; it gets read, distilled and explicitly linked into the existing network. The result is structured Markdown pages with cross-references, open questions and documented contradictions. The expensive work is already done at intake. A query fetches finished thoughts, not raw ingredients.
The differences in practice
RAG finds a similar chunk. Compiled knowledge delivers a finished page that has already related source A to source B - including the places where they contradict each other. And while RAG starts from zero with every query, every new source further enriches the compounding network: each cross-reference increases the value of the pages that are already there.
Where the model hits its limits
To be honest: in my setup, Mycel currently runs without any embedding infrastructure. That works as long as the knowledge network stays manageable and the links are kept clean. Does it scale to tens of thousands of pages? Probably not without a hybrid approach - compiled knowledge as the curated base, embeddings as a full-text fallback for whatever hasn’t been distilled yet. I haven’t pushed it to the limit yet. Anyone who claims one model solves every case is selling something.
But even a perfectly maintained, compiled wiki doesn’t solve the actual problem. Having a page that contains exactly the answer is useless if it doesn’t get pulled up at the right moment. Storage is only half the battle. The other half is retrieval.
30 well-linked pages are worth more than 200 isolated summaries. But both are worthless if they aren’t present at the decisive moment.
The real problem was never collecting
We had solved everything. A wiki that maintains itself. Compound growth instead of an expiry date. No more contradictions swept under the rug, no three half-baked notes on the same topic, no graveyard of Markdown files. On paper, the problem was solved.
And yet.
I had maintained my knowledge, linked it, synthesized it - and in the moments when it counted, it didn’t come to mind. In the meeting, in the architecture decision, in the quick code review. It just wasn’t there. It sat in the wiki, neatly sorted, perfectly linked, and helped me exactly zero.
Retrieving knowledge is a different discipline from storing knowledge. That’s the uncomfortable insight. Storing is asynchronous, controlled, unhurried. Retrieving happens under pressure, mid-conversation, in the second the decision gets made.
The classic PKM debate has a blind spot: it revolves almost entirely around input. How do I organize? Which system? Atomic notes or Folgezettel? Tags or folders? The other half - what do I pull out in which situation? - stays unanswered. As if retrieval were a solved by-product of clean storage. It isn’t.
With thinking tools, this gets painfully concrete. I know inversion. I know second-order thinking. I know Ishikawa, pre-mortem, opportunity cost. I’ve read books about them, taken notes, linked them. And I still don’t apply them when I need them.
Mental models activate System 2 thinking - the slow, deliberate, analytical kind. The catch: under pressure, System 1 takes over. Fast, reflexive, pattern-driven. At least that’s the popular reading of Kahneman. The book on the shelf doesn’t help in the meeting. The note in the wiki doesn’t help in the pull request discussion. And that’s exactly the gap classic PKM never addressed: between “I know the concept” and “I use it at the right moment”.
The consequence is uncomfortable, but clear. Collecting more knowledge doesn’t solve this problem. Organizing it better doesn’t either. Even a perfectly LLM-maintained Mycel wiki stays passive - it waits until I ask. And at the decisive moment, that’s exactly what I don’t do.
What it takes is something else: thinking tools that are available at the right moment. Not as a book, not as a note, not as a chapter in the wiki. As a skill on demand.
Collecting knowledge is half the battle. Activating it at the right moment is the rest - and the harder part.
Thinking tools on demand
“Skill on demand” sounds abstract, so let me make it concrete: a thinking tool only becomes a tool once it’s within reach in the situation where I need it. Not ten minutes later. Not after the meeting. Not when it occurs to me in the evening that I really should have inverted that morning.
That was exactly my problem with frameworks for years: I knew them. I had even written them down and distilled them, dutifully following CODE. And still they weren’t there at the moment of decision.
untools.co as raw material

Adam Amran, a product designer from the Czech Republic, curates more than 25 thinking tools on untools.co in four categories: Decision Making, Problem Solving, Systems Thinking and Communication. The mission statement is dry: “Collection of thinking tools and frameworks to help you solve problems, make decisions and understand systems.”
As a bookmark, the site is useless. As ingested raw material in my Mycel - concept pages per tool, plus one Claude skill per tool, plus a synthesis page as a navigator - it’s something else.
Inversion
Don’t ask “how do I achieve X?” but “how could I guarantee that X fails?”. The list of things to avoid is often more concrete than the list of paths. Typical use: a pre-mortem before a decision.
Second-order thinking
“And then what?” Don’t stop at the first consequence; think through the cascade of effects. Kicks in when a decision looks obviously good - that’s usually the signal to think at least two levels further.
Issue trees
A MECE-structured breakdown of a problem into sub-problems, then an 80/20 focus on the branches with the biggest leverage. Kicks in when a problem seems too big to tackle.
Eisenhower Matrix
Four quadrants built from importance and urgency. It was popularized by Stephen Covey in “7 Habits” (Habit 3: Put First Things First). Sounds trivial, but it’s the most precise filter I know for weekly planning - especially for honestly naming “urgent but unimportant”.
The decisive shift
The navigator works like a routing layer. I describe the situation: “The problem is too complex, I don’t know where to start.” Suggestion: issue trees. “I only see ideal solutions.” Suggestion: inversion. “The decision feels right too quickly.” Suggestion: second-order thinking.
I no longer have to know which tool I need. I just have to describe my situation. The rest is navigation - and the assistant handles that.
A framework I can’t activate at the right moment isn’t a tool. It’s a keepsake.
Integration into routines - the Phoenix Progression
My own productivity routine - I call it the Phoenix Progression - combines the 12 Week Year principle by Moran and Lennington (“In 12 weeks, there just isn’t enough time to get complacent, and urgency increases and intensifies.”) with a cyclical rhythm across five time layers: Era (5 years), Cycle (6 months), Firestorm (12 weeks), Week Fire (1 week), Flame (2 hours).
Each layer has its own rituals. And it’s exactly in these rituals that the thinking tools plug in.
For a Flame - a two-hour deep work block - I get suggestions at the start for methods that fit the situation. For Week Fire reviews, different ones. For the Firestorm retrospective, inversion gets suggested as a pre-mortem for the next cycle. In daily planning, the Eisenhower Matrix comes into play when the list gets too long. In cycle planning, first principles, when I notice that I’m just extending goals instead of rethinking them.
I don’t call these up. The skill chimes in when the situation fits - the method grows out of the mycelium as a fruiting body at the right moment.
The difference is subtle, but decisive: the cognitive effort of even thinking of the right framework disappears. The framework is no longer on the shelf. It’s in the situation - as a skill that gets loaded when the context is right.
No “I should have thought of inversion”. No digging through old notes. The skill does the remembering.
Sounds finished. It isn’t.
What’s changing right now - and what doesn’t work (yet)
What I describe above is an ongoing negotiation - not a finished productivity solution you can copy.
What’s changing right now
Writing notes feels different. I collect less. Not because I read less, but because I know the LLM maintainer condenses at ingest. I no longer have to capture every passage verbatim so I can find it later. That changes what I consider worth noting.
Thinking in frameworks has gotten easier. Not because I know more frameworks - but because they show up at the right moment. A dialectic skill that speaks up when I have to make a decision is something different from a book on the shelf that I’d have to actively consult.
Connections show up that I would never have seen. Ingest creates wikilinks I wouldn’t have come up with on my own. Some are trivial, some change how I place a topic. That’s the part that feels most like compiling and least like search.
And there are open questions. How does this scale beyond 500 pages when connections grow exponentially? What happens if I want to fundamentally change the schema - does the maintainer migrate the wiki, or does it start from zero? I don’t know.
This isn’t a finished productivity system you copy. It’s an ongoing negotiation between me and a machine that keeps getting better at condensing knowledge. And keeps getting better at taking work off my hands that maybe I shouldn’t hand over at all. The leverage lies in the division of labor. I decide what matters, what stays, which direction the whole thing takes. The machine distills, links, and serves things up when the situation calls for it. Holding that line is work - and it’s the actual job.
The point isn’t to know more. The point is to have the right thing present at the right moment.
The human curates, the machine compiles.